Concept overview
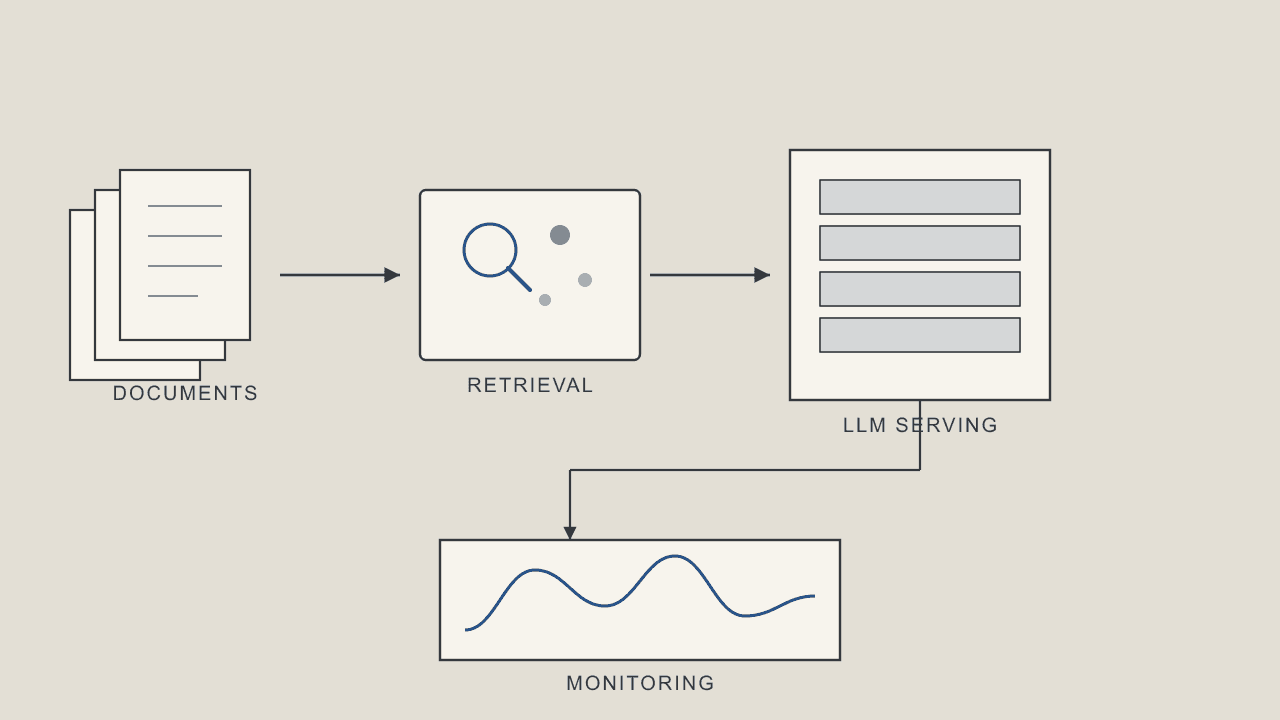
This is a sample/demo entry used to test the portfolio layout, not a completed professional project. It outlines a retrieval-augmented generation pipeline: document ingestion, chunking, and vector retrieval feeding a serving layer such as vLLM or KServe.
RAG evaluation and observability (for example Langfuse or OpenTelemetry) are included in the concept so that retrieval quality and generation behaviour could be tracked over time.
Intended deployment direction
Deployment is envisioned with Docker and Kubernetes, with Kubeflow and CI/CD handling repeatable builds and rollouts.
No measured latency, accuracy, publications, or production traffic are claimed; this entry exists to demonstrate layout and content structure only.